See inside a Transformer model token by token
You can now watch an AI model calculate its next word in real time.
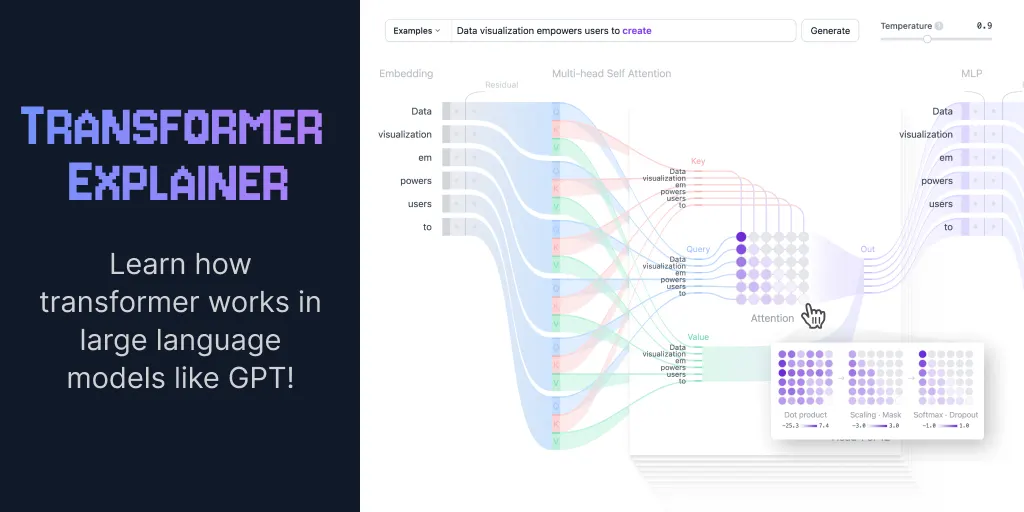
Transformer Explainer is an interactive visual tool that reveals how Transformer models process text. Built on top of GPT-2 (small), a 124-million parameter model, the playground lets you enter a prompt and trace data through the entire architecture. The tool caught traction on Hacker News with 178 points.
Why it matters: Flagship models like OpenAI's GPT, Meta's Llama, and Google's Gemini all rely on the same Transformer architecture. Seeing how a smaller model processes vectors across its internal blocks makes complex concepts like self-attention and positional encoding clear in seconds.
Here's the gist of how the tool breaks down the pipeline:
- Embedding: Splits text into tokens from a 50,257-entry vocabulary, maps them to 768-dimensional vectors, and adds positional encodings.
- 12 Transformer Blocks: Uses self-attention to share context between tokens, then uses feed-forward layers to refine each token.
- Output Probabilities: Converts processed embeddings into final token predictions.
Turns out neural networks aren't black boxes, just structured math running in sequence.
Sources
- Transformer Explainer — https://poloclub.github.io/transformer-explainer/
- Hacker News — https://news.ycombinator.com/item?id=49792342